Data Warehouse, Data Lake, and Data Lakehouse are all
concepts in the realm of data storage and management,
each serving distinct purposes. They represent the evolution of data storage philosophy.
Data Warehouse:
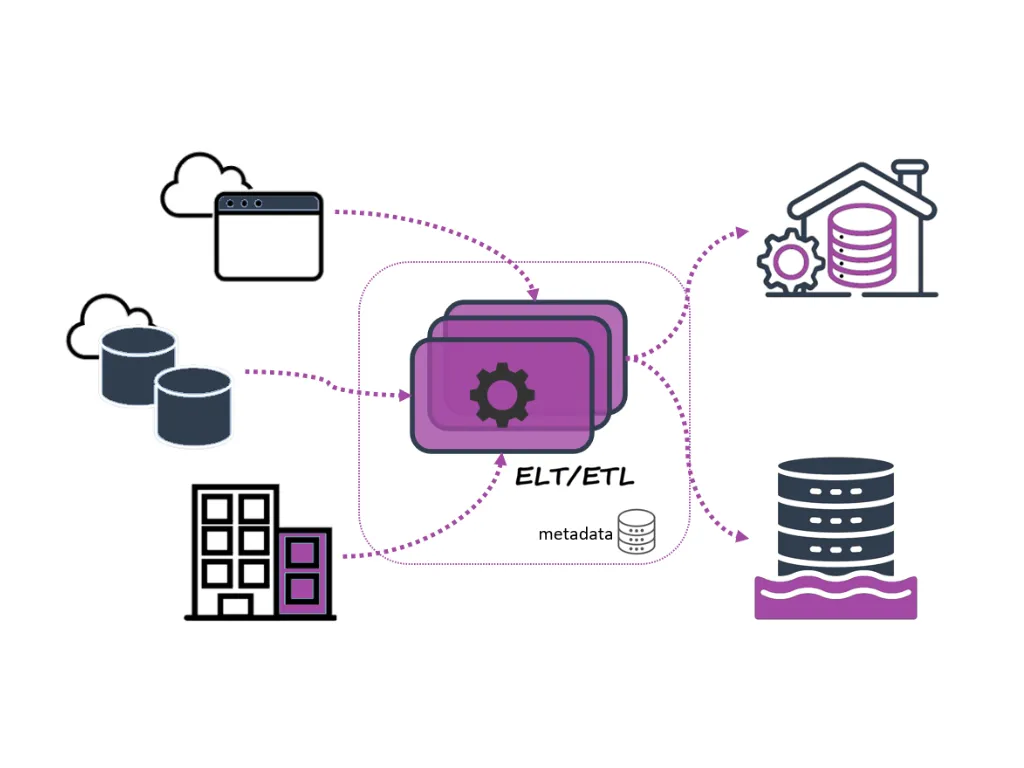
A Data Warehouse is a traditional standard, a centralised repository that
consolidates data from various sources, transforming
and organising it for efficient querying and analysis. It stores structured data (rows and columns) that
has been processed and cleaned. It is like a filing cabinet, everything must be filed correctly
before it can be stored. It is optimised for fast, reliable reporting (Business Intelligence)
but is expensive and inflexible with new data types.
Data Lake: A response to the Big Data explosion.
It is a vast, scalable storage repository that houses both structured and unstructured data.
It stores raw data in its native format (documents, images, logs, JSON).
It is like a massive reservoir, where you can dump anything in without processing it first.
It is cheap and scalable but can become a "Data Swamp" if not managed, making retrieval difficult.
It acts as a catch-all for diverse data types and allows for
data exploration, enabling data scientists and
analysts to delve into the data without prior
structuring.
Data Lakehouse: The modern hybrid.
It combines the low-cost, flexible storage of a Data Lake with the structure, management, and
performance features of a Data Warehouse. It allows for ACID transactions (reliability) on top of raw data,
supporting both BI (reporting) and AI (machine learning) workloads on a single platform.
The Lakehouse architecture strives to make data processing and
analytics more streamlined and accessible, allowing
for near-real-time data insights without compromising
on data reliability.
 Vilko Poznovia