Every report, forecast and AI answer is only as good as the data behind it. "Garbage in, garbage out" is an old saying, but it matters more now that data feeds automated decisions and AI assistants as well as dashboards. Poor data quality rarely announces itself: it shows up as a stock shortage, a duplicated mail-out or a number nobody in the meeting trusts.
This article explains what good data looks like, where quality usually breaks, and a practical way to keep your data accurate and reliable.
Why data quality matters
- Decisions: a retailer ordering for the holiday season from inaccurate sales history either ties up cash in stock that doesn't sell, or runs out of what customers want.
- Safety and trust: in healthcare, a missing or wrong allergy record can lead to a harmful prescription. In any sector, errors in customer records erode trust quickly.
- Efficiency: duplicate customer records mean the same person gets the same promotion three times, analytics overstate the customer base, and staff spend time reconciling records instead of using them.
- Compliance: under Australian Privacy Principle 10, organisations must take reasonable steps to make sure the personal information they collect, use and disclose is accurate, up to date and complete.
What good data looks like: six dimensions
Data quality is easier to manage once you break it into dimensions you can measure. Microsoft Purview, for example, measures six common ones:
- Accuracy: the data correctly represents the real-world thing it describes.
- Completeness: the values that should be there are there, without empty or missing fields.
- Conformity: values follow the expected format and rules, such as a valid postcode or date.
- Consistency: the same fact matches across systems, so a customer's status is the same in billing and CRM.
- Timeliness: the data is up to date enough for the decision it supports.
- Uniqueness: each real-world record appears once, without duplicates.
Not all data needs the same care. Focus first on the critical data elements behind your most important decisions and reports, such as customer, product and financial data, and set quality targets for those.
Where quality usually breaks
- At entry: free-text fields, missing validation and workarounds in forms.
- Between systems: integrations that map codes differently, or drop records that fail silently.
- During migrations: legacy data moved without profiling, cleansing or reconciliation.
- Over time: addresses, contacts and reference data go stale unless someone owns them.
- In AI: models and assistants repeat whatever errors and biases are in the data they learn from or retrieve.
How to keep data accurate and reliable
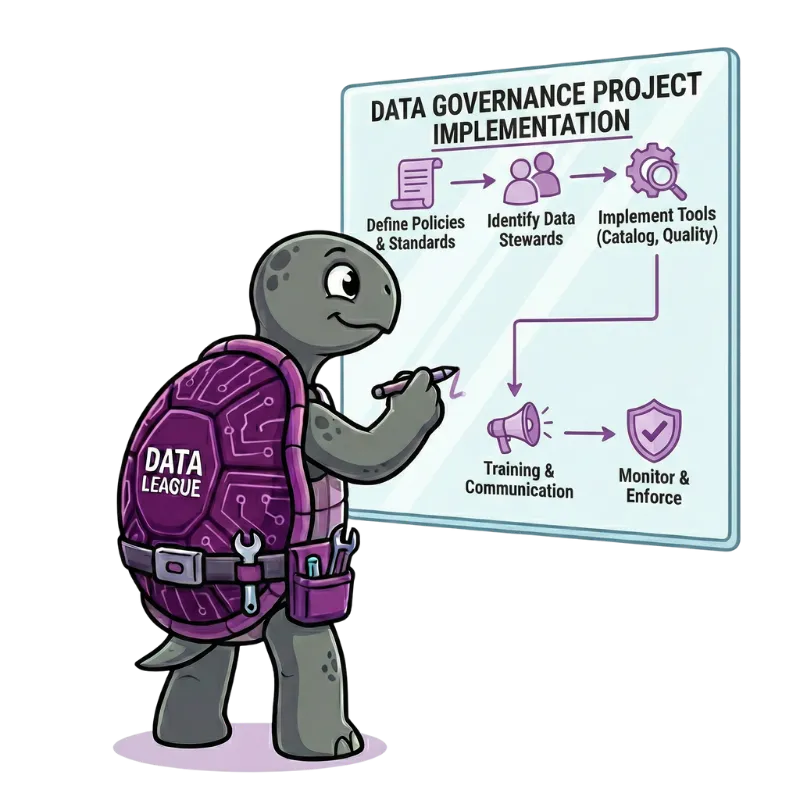
- Pick your critical data. Start with the data behind the decisions and reports that matter most.
- Give it owners. Name a business owner and a data steward for each critical data set, so issues have somewhere to go.
- Define rules and targets. Turn each relevant dimension into a rule you can test, such as "every active customer has a valid email", with a target pass rate.
- Measure automatically. Run the checks inside your data pipelines and publish the scores, so problems are found before they reach a report.
- Fix at the source. Correct the system or process that created the error, not just the copy in the warehouse.
- Prevent repeats. Add validation at entry, use shared reference data, and match and merge duplicates.
- Review regularly. Track the scores over time and raise targets as quality improves.
Data quality and AI
AI raises the stakes. An assistant that answers from your documents will confidently repeat an outdated policy, and a model trained on biased or incomplete history will reproduce that bias at scale. The OAIC's guidance for organisations developing and training AI models singles out APP 10, noting that accuracy obligations apply to the data used and to what the model produces about real people. Good data quality isn't a separate project from AI; it's the foundation for it.
Need help? Our data governance consultants set up ownership, quality rules and monitoring, and our migration team profiles and reconciles data so quality improves when you move platforms. Comparing tools? See our guide to Microsoft Purview vs OvalEdge.
Our four-week Data Governance Quick Start includes your critical data elements, quality rules and a first data quality dashboard.